Free workflow download
Free for members. Create a free account or log in to download.
Give it one photo and one voice recording, and LongCat Avatar 1.6 turns them into a talking video with real lip sync. The head moves, the eyebrows follow the words, and the person stays the same from the first second to the last.
LongCat-Video-Avatar 1.6 is the new open model from the Meituan LongCat team, released under the MIT license. It had no ComfyUI support yet, so we built the nodes: ComfyUI-LongCat-Avatar-PixelAILabs. They run the official INT8 model in 8 steps, and the video is as long as your audio.
Below you'll find three example videos with the photo and the prompt behind each one, every model with its download link, the settings that matter and the speed on an RTX 5090. The free workflow is in the download section.
What LongCat Avatar 1.6 does
It's an audio-driven video model. You don't animate anything by hand: the voice drives the mouth, the face and small head movements, and your prompt sets the scene and the mood.
Version 1.6 builds on 1.5 with more natural mouth movements, better lip-to-audio sync and face and body motion that work together. It also has a new 8-step mode, made with two LoRAs that the official release ships with the model. Our Model Loader switches between them for you.
Long videos are made window by window: each window is 93 frames (about 3.7 seconds), and the next one continues where the last one stopped. So the same workflow makes a 4-second test or a full minute.
3 talking avatar videos with their prompts
Each video is one run from one photo and one voice line made with ElevenLabs, at 480p and seed 42. No LoRA, no face swap and no editing; they are only upscaled to 720p for this page. Turn the sound on.
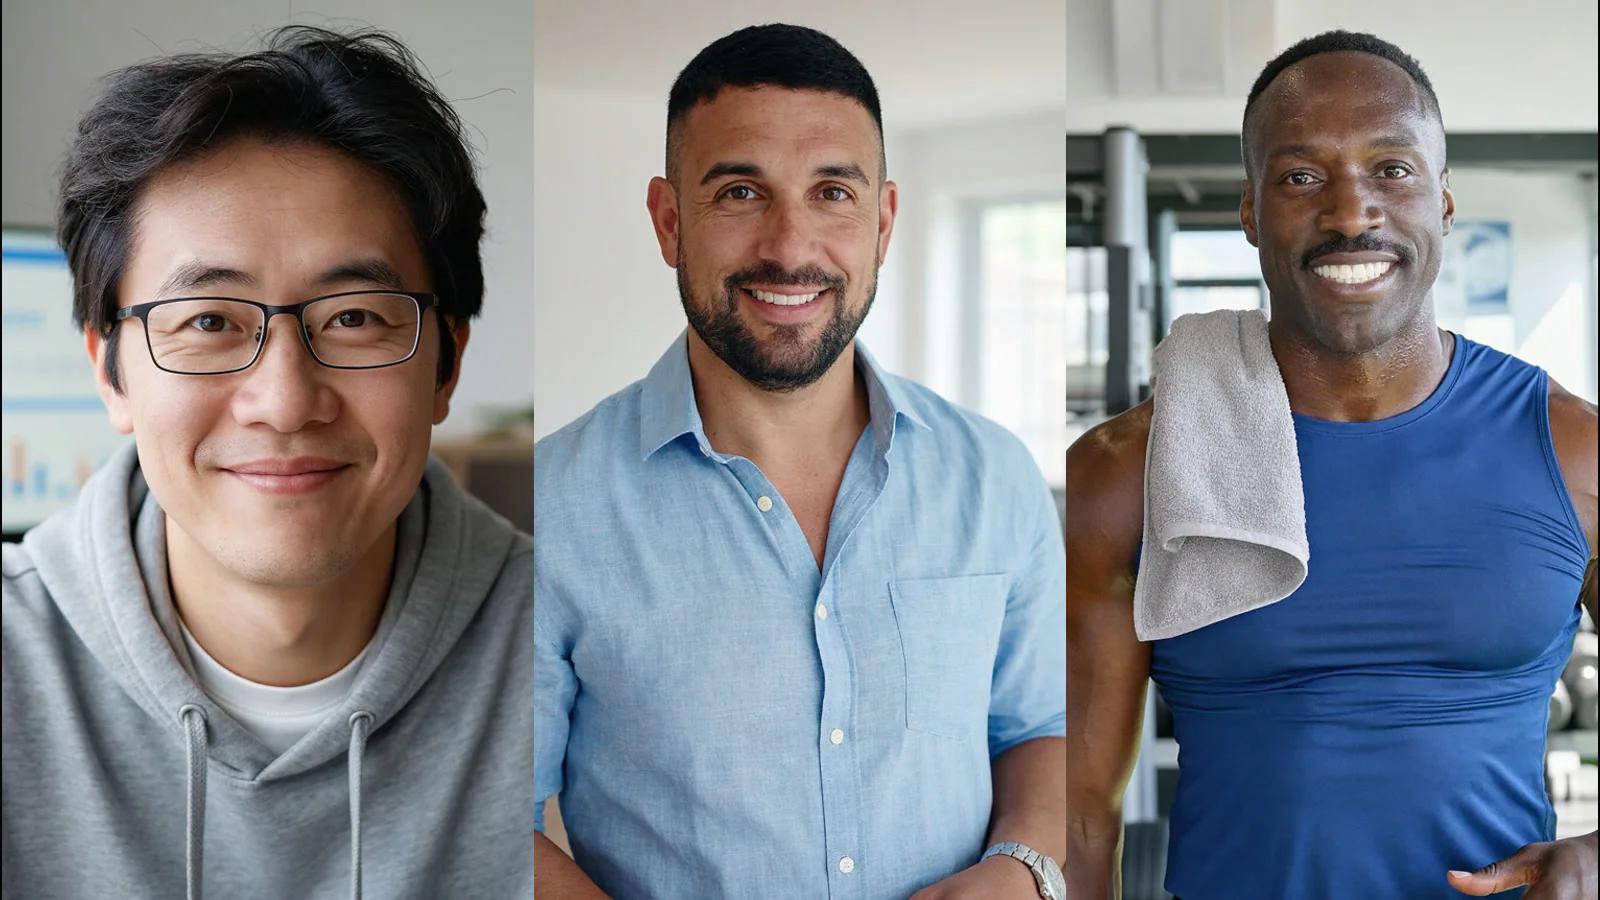
1. Tech creator (8.7 s)
A home office with a monitor and bookshelves behind him. Watch the eyebrows and the small nods: they follow the words, not a loop.
A friendly East Asian man in his thirties with short messy black hair and thin black glasses, wearing a grey hoodie over a white t-shirt, sits at his desk in a bright home office and talks straight to the camera like a tech YouTuber. A monitor with a dashboard, a desk lamp and bookshelves are softly blurred behind him. He speaks casually and confidently, small natural head movements, eyebrows move with the words, a relaxed smile, hands stay out of frame. Soft daylight from a window, static camera on a tripod, medium close-up.2. Real estate agent (9.1 s)
A calm, warm delivery in an empty living room. His hands stay relaxed at his waist because the prompt asks for it.
A confident man in his thirties with short dark hair and a trimmed beard, wearing a light blue linen shirt with rolled sleeves, stands in a bright empty modern living room with large windows and a grey sofa, and talks straight to the camera like a real estate agent giving a house tour. He speaks warmly and clearly, a welcoming smile, small natural head movements, hands relaxed at his waist. Soft natural daylight, static camera on a tripod, medium shot from the waist up.3. Fitness coach (8.9 s)
High energy in a gym. Lively expressions and a big smile, while the face and the towel stay the same all the way through.
An energetic athletic Black man in his forties with very short hair and a big smile, wearing a blue sleeveless training top with a white towel over one shoulder, stands in a bright gym with racks of dumbbells and squat racks softly blurred behind him, and talks straight to the camera like a fitness coach. He speaks with high energy and motivation, lively expressions, nods and small head movements, arms relaxed. Bright daylight, static camera on a tripod, medium shot from the waist up.What you need
- ComfyUI and the Python that comes with it.
- An NVIDIA GPU with 32 GB of VRAM. We tested on an RTX 5090 (32 GB) with 64 GB of system RAM. We have not tested smaller cards yet, so we can't promise they work.
- About 31 GB of free disk space for the models.
1. Install the nodes
In the ComfyUI Manager, open Custom Nodes Manager, choose Install via Git URL and paste https://github.com/Pixelailabs/ComfyUI-LongCat-Avatar-PixelAILabs. Then restart ComfyUI. Or install it by hand:
cd ComfyUI/custom_nodes
git clone https://github.com/Pixelailabs/ComfyUI-LongCat-Avatar-PixelAILabs
cd ComfyUI-LongCat-Avatar-PixelAILabs
pip install -r requirements.txt
Use the Python of your ComfyUI. On the Windows portable version that's ..\..\..\python_embeded\python.exe -m pip install -r requirements.txt. For more speed, also run pip install sageattention.
2. The models
You only download the text encoder yourself. The Model Loader and Whisper Loader download the rest on the first run (about 25 GB) into ComfyUI/models/longcat.
| What | File | Folder | Size |
|---|---|---|---|
| Text encoder | umt5_xxl_fp8_e4m3fn_scaled | text_encoders | 6.7 GB |
| LongCat Avatar 1.6 INT8 model + 2 LoRAs | automatic | longcat/LongCat-Video-Avatar-1.6 | 21 GB |
| Whisper large-v3 (reads the voice) | automatic | longcat/LongCat-Video-Avatar-1.6/whisper-large-v3 | 3.1 GB |
| LongCat VAE | automatic | longcat/LongCat-Video/vae | 0.5 GB |
Want to download by hand? From LongCat-Video-Avatar-1.6 take only base_model_int8/, loraA/, loraB/, scheduler/, config.json and whisper-large-v3/model.safetensors, and the vae/ folder from LongCat-Video. You don't need the full 77 GB repo.
3. Load the workflow
Drag LongCat_Avatar_1.6_PixelAILabs.json onto the ComfyUI canvas. Every node is already connected.
How to make your first talking avatar
- Load Image: a photo of your avatar, framed the way you want the video. Chest up works best.
- Load Audio: clean speech with no music. The video is exactly as long as the audio, and an ElevenLabs line is perfect.
- Text Encode: one short paragraph about who it is and where, ending with "static camera on a tripod".
- Press Run. The video with the voice is saved in
ComfyUI/output/.
The nodes and the settings that matter
| Node | What it does |
|---|---|
| Model Loader | Loads 1.6 (or 1.5), INT8 or bf16, and downloads missing files |
| Text Encode | Your prompt, through a Load CLIP node (UMT5, type wan). It runs on the CPU |
| Whisper Loader + Audio Encode | Turn the voice into lip-sync data. Keep model_version on 1.6 |
| Vocal Extract | Optional: takes the voice out of a song or a noisy clip |
| Sampler | Makes the video, window by window |
| Setting | Node | Default | What it changes |
|---|---|---|---|
attention_mode | Model Loader | auto | Picks SageAttention, then FlashAttention 2, then PyTorch |
mix_steps / mix_alpha | Model Loader | 4 / 1.0 | The official 1.6 LoRA switch. mix_steps 0 is about 15% faster but uses more VRAM |
resolution | Sampler | 480p | 720p is about 3× slower per step |
block_num | Sampler | 1 | 1 streams the model through the GPU. 0 loads all of it: faster, but needs far more VRAM |
Speed on an RTX 5090
Tested on Windows with an RTX 5090 (32 GB) and 64 GB of RAM, at 480p:
| Setup | Time for a 3.8 s clip |
|---|---|
| auto attention, before installing SageAttention | 7.7 min |
| SageAttention | 6.6 min |
SageAttention + mix_steps 0 | 5.6 min |
Every extra 3 seconds or so of audio adds one window, which takes about 1.5 to 2.5 minutes at 480p.
Low VRAM and low RAM tips
- Keep
block_numon 1,mix_stepson 4 and the size on 480p. With streaming, the model itself took about 13 GB of VRAM at 480p on our card. - Close other apps that use the GPU, like video editors or a browser with many tabs. They can take 5 GB and cause out-of-memory errors.
- Out of memory with
mix_steps0? Go back to 4. - Use the fp8 text encoder and leave the Text Encode
offload_deviceon cpu. - With streaming, the INT8 model and the LoRAs wait in system RAM, about 21 GB. 64 GB of RAM is comfortable; 32 GB is tight.
Make your own AI influencer
Want one consistent AI influencer who looks the same in every photo and talking video? That's what my AI Influencer Pro course covers, step by step: her own LoRA, KREA 2 photos and MiniMax H3 talking videos, on your own GPU or the course cloud.
Downloads
The workflow is free in the Free workflow downloads box at the top of this page (on a phone, just under the cover picture). Create a free account or log in, click the file, then drag the JSON onto the ComfyUI canvas. The nodes themselves are on GitHub: ComfyUI-LongCat-Avatar-PixelAILabs. If they save you hours, a star on the repo helps a lot.
Credits
- LongCat-Video-Avatar 1.6 by the Meituan LongCat team (MIT license)
- Built on the 1.5 node pack ComfyUI-LongCat-Avatar by rookiestar28 (MIT license)
- SageAttention. The voices were made with ElevenLabs.